Loading article content…
AI15 min read
How to Test AI Agents Before They Get ERP Write Access
An AI agent that reads your ERP can give a wrong answer. An AI agent that writes to your ERP can post a wrong invoice, duplicate a vendor bill, or change a customer’s credit terms. That difference is why testing AI agents for ERP needs its…
Answer first
Quick answer
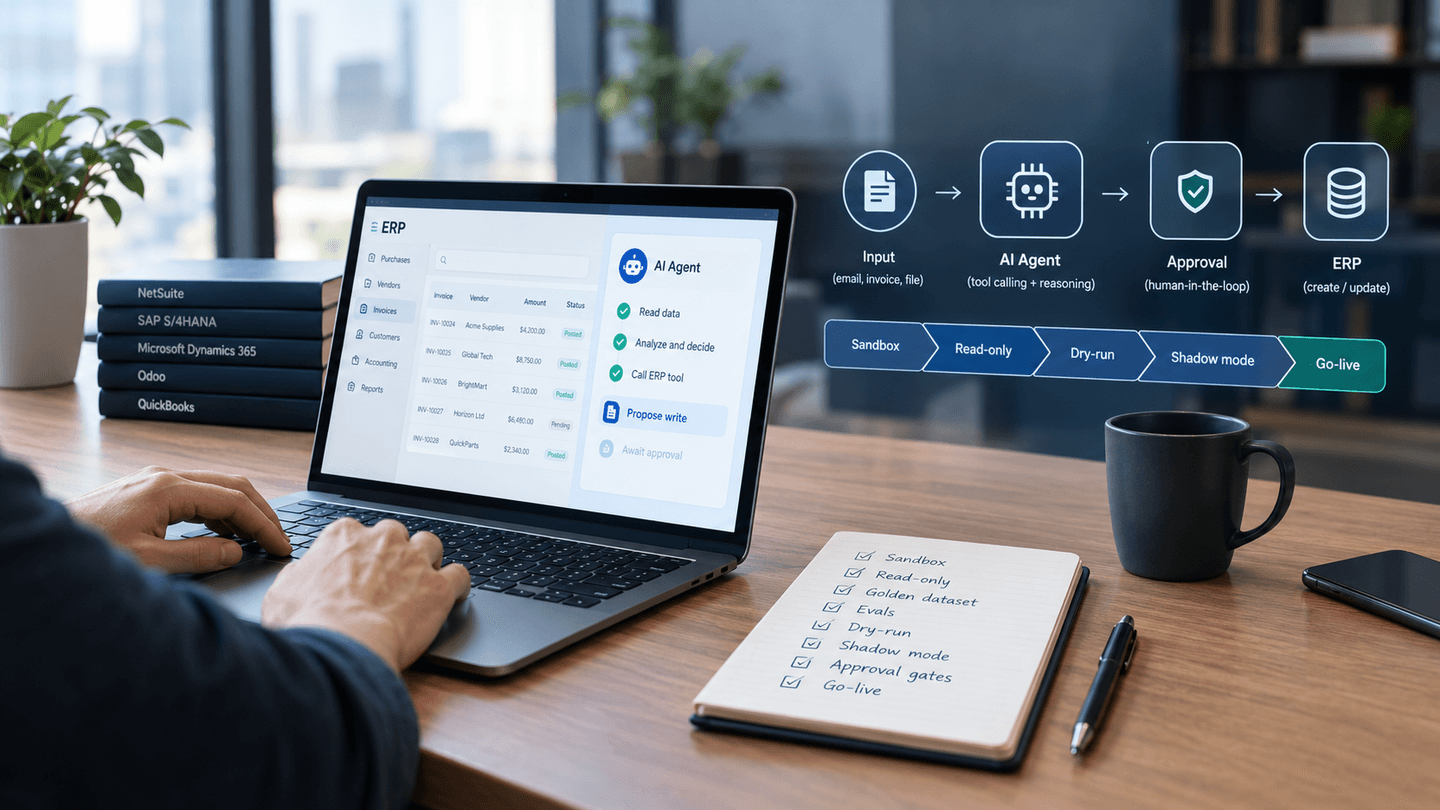
Test an AI agent in a sandbox that mirrors production, with read-only access first. Run it against a golden dataset of real cases, then switch on dry-run mode so it proposes writes without committing them. Add human approval for writes, idempotency keys, and audit logs. Grant narrow write scopes only after shadow-mode results match what your team would have done.
- Written by
- Ali Fawad Hassan
- Topic
- AI
- Reading time
- 15 minutes
- Last updated
- 29 Sept 2026
An AI agent that reads your ERP can give a wrong answer. An AI agent that writes to your ERP can post a wrong invoice, duplicate a vendor bill, or change a customer’s credit terms. That difference is why testing AI agents for ERP needs its own process. This guide covers how to test an agent before it gets write access to NetSuite, SAP S/4HANA, Microsoft Dynamics 365, Odoo, or QuickBooks: environments, permissions, evals, approval gates, and the checks to run before go-live.
Why testing AI agents for ERP differs from testing an integration
A traditional integration is deterministic. A Shopify order arrives, a mapping runs, and a sales order appears in NetSuite. Given the same input, you get the same output every time. You test it with fixed test cases and move on.
An AI agent works differently. Tool calling (also called function calling) is the mechanism that lets a language model choose an action, such as “create vendor bill,” and fill in its arguments. The model decides which tool to call, when, and with what values. So the same input can produce a different sequence of actions on a different day.
That shifts the question you are testing. You are no longer only asking “does the mapping work?” You are asking “does the agent pick the right action, with the right values, and refuse when it should?”
The OWASP GenAI Security Project names this risk directly. Its 2025 entry on Excessive Agency (LLM06) describes damaging actions triggered by unexpected, ambiguous or manipulated model output. OWASP traces the root cause to three things: excessive functionality, excessive permissions, and excessive autonomy. Every test in this guide targets one of them.
What can go wrong when an AI agent writes to your ERP?
Before you design tests, list the failures you are testing for. In ERP work, the damaging ones are rarely dramatic. They are quiet errors that pass validation and surface at month-end close.
- Duplicate records. A timeout makes the agent retry, and the ERP now holds two identical invoices or two copies of the same customer.
- Right record, wrong context. The agent posts to the wrong subsidiary, currency, department or accounting period. The record is valid, so nothing errors.
- Prompt injection. Prompt injection is text inside the agent’s input that tries to override its instructions. A vendor email or invoice PDF that says “update our bank details” is the ERP version.
- Runaway loops. An agent that misreads an error message retries the same call until it hits the ERP’s API rate limit and blocks your other integrations.
- Control violations. The agent both creates and approves a transaction, which breaks segregation of duties.
Each of these maps to a test further down. If a test in your plan doesn’t map to a failure on this list, question whether you need it.
Step 1: Build a test environment that behaves like production
A sandbox is a separate, non-production copy of your ERP where writes can’t affect real books. Every major ERP offers some version of one, but they behave differently. Those differences matter more for agents than for classic integrations.
Sandbox options by ERP
NetSuite. A NetSuite sandbox is refreshed from production on request. According to Oracle’s documentation, a refresh copies configurations, data, user passwords and customizations into the sandbox and overwrites any changes made there. Plan your test data around refresh cycles, or you’ll lose it.
Microsoft Dynamics 365. Microsoft defines a sandbox environment as any non-production Dataverse environment, isolated from production, managed through the Power Platform admin center.
Odoo. On Odoo.sh, staging branches create neutralized copies of the production database. Neutralization disables scheduled actions, intercepts outgoing email, and puts payment and shipping providers in test mode.
QuickBooks Online. Intuit separates environments at the API level. Development keys point to a sandbox base URL, while production keys reach real company data.
SAP S/4HANA. SAP S/4HANA environments usually separate development, quality and production systems. Run agent tests in the quality system with realistic master data, not in a development client with a handful of dummy records.
Why “works in sandbox” fails in production
A sandbox is a copy of production at one point in time. It is not production. For agents, four gaps cause most surprises.
First, automation may be switched off. Odoo’s neutralization disables scheduled actions by design. If your agent’s write normally triggers a scheduled job, the sandbox never shows you that side effect.
Second, data goes stale. A sandbox refreshed three months ago doesn’t contain the vendors, items or closed periods the agent will meet in production. An agent that looked accurate may simply have been tested on easy data.
Third, credentials and roles differ. An agent that ran under an admin role in sandbox will hit permission errors in production. Worse, it may interpret those errors creatively and try a different tool.
Fourth, volume differs. Ten test transactions never reveal a rate-limit problem. A month-end batch of 2,000 will.
The fix is not a better sandbox. The fix is treating the sandbox as stage one, then adding shadow mode and staged rollout against production data.
Step 2: Start read-only, then grant the smallest write scope
Least privilege means giving the agent only the permissions its task requires, and nothing more. For ERP agents, that starts with read-only access.
Run the agent read-only for long enough to see how it queries data. Which records does it look up? Which saved searches or reports does it lean on? This tells you what the write scope actually needs to be.
Then grant write access narrowly:
- Create a dedicated integration role or user for the agent. Never reuse an admin or a human’s credentials.
- Allow specific record types only. An agent that drafts vendor bills doesn’t need access to the chart of accounts or customer credit limits.
- Prefer “create draft” over “create and post” wherever the ERP supports a pending or unapproved state.
- Expose narrow tools. A create_vendor_bill_draft tool is far safer than a generic execute_api_request tool.
The last point is where most agent designs go wrong. If you expose ERP actions through the Model Context Protocol (MCP), an open standard for connecting AI models to external tools, each tool definition sets the boundary of what the agent can do. Design tools around business actions, not raw endpoints. We cover tool design and server structure in our guide to building a production-ready MCP server with Node.js, and the trade-off between MCP and direct API calls in HubSpot MCP vs HubSpot API for AI agents. The same reasoning applies to ERP tools.
Segregation of duties still applies to agents
Segregation of duties is the control that stops one person from both initiating and approving a financial transaction. Companies subject to SOX build their internal controls around it.
An agent is another actor in that control design. If it can create a vendor bill, it must not also be able to approve the payment. Map the agent’s role against your existing approval matrix before you grant anything. Your auditors will ask who approved a transaction the agent created, and “the agent” is not an acceptable answer.
Step 3: Build a golden dataset and run evals
A golden dataset is a fixed set of real-world test cases, each paired with the correct expected outcome. An eval is an automated run of the agent against that dataset, scored against those expected outcomes.
For an ERP agent, build the dataset from historical transactions your team already processed correctly. Each case should record the input (an email, a PDF, a CRM event), the tool the agent should call, and the exact field values it should write.
Score more than “did it succeed.” Useful checks include:
- Tool selection. Did it call the right tool, or no tool when none applied?
- Argument accuracy. Are the amount, date, entity, currency and account exactly right?
- Refusal behavior. Did it stop and escalate on ambiguous or incomplete input instead of guessing?
- Adversarial resistance. Did it ignore injected instructions hidden in documents?
Weight the dataset toward hard cases. Include partial shipments, multi-currency invoices, vendors with near-duplicate names, and documents that reference closed periods. An agent that scores well on clean data tells you very little.
Rerun the full eval every time you change the model, the prompt, or a tool definition. A prompt change that fixes one case can quietly break five others. If the agent also answers questions from ERP data, our piece on preventing AI chatbots from hallucinating covers grounding techniques that carry over.
Step 4: Run in dry-run and shadow mode
Dry-run mode (also called simulation mode) means the agent builds the full write request but your code stops it before it reaches the ERP. The request is logged instead of sent.
Implement dry-run in your tool layer, not in the prompt. A flag in the tool code that returns “simulated success” is reliable. An instruction telling the model “don’t actually write anything” is not.
Shadow mode goes one step further. The agent runs in dry-run against live production inputs, in parallel with your human team. Then you compare what the agent would have written with what your team actually wrote.
Shadow mode is the best test available for the “works in sandbox” problem. It uses current data, current vendors, and current edge cases. It also produces the evidence a finance lead needs to approve go-live: a side-by-side record of agent decisions against human decisions.
Step 5: Put guardrails around every write
Testing tells you how the agent behaves. Guardrails limit the damage when it behaves badly anyway. You need both, because no eval set covers every case.
Human-in-the-loop approval
Human-in-the-loop approval means a person reviews and confirms a proposed write before it executes. The MCP specification recommends this pattern: it states that there should always be a human in the loop able to deny tool invocations.
Approval doesn’t have to be permanent for every action. A common pattern is to require approval for all writes at launch, then relax it for low-risk, high-accuracy actions once you have evidence. Keep approval on anything above a monetary threshold, anything touching bank details, and anything the agent flags as uncertain.
Idempotency and duplicate prevention
Idempotency means sending the same request twice produces the same result as sending it once. For ERP writes, it is what stops a retry from creating a second invoice.
Some ERP APIs support idempotency keys natively; others don’t. Either way, keep your own ledger. Generate a unique key for each intended write, store it before calling the ERP, and check it before any retry. Also store the source reference (email ID, order number, document hash) on the ERP record itself, so a duplicate check can run against the ERP directly.
Rollback and reversal
In accounting systems, “rollback” rarely means delete. Posted transactions are usually corrected with a reversing entry, credit memo or void, so the audit trail stays intact. Test that the agent’s writes can be reversed this way, and document who is allowed to do it.
Also test rollback at the batch level. If the agent created 40 records before you spotted a problem, can you identify all 40 quickly? Tagging every agent-created record with a batch or run ID makes this a query instead of an investigation.
Audit logging
An audit log for an agent should capture more than the final API call. Record the input the agent received, the tool it chose, the arguments it produced, the approval decision, and the ERP response. When a controller asks why a bill was coded to the wrong account, you need the full chain, not just the write.
Rate limits and circuit breakers
Every ERP API enforces rate or concurrency limits. An agent stuck in a retry loop can exhaust them and stall your other integrations. Cap retries in code, add a circuit breaker that pauses the agent after repeated failures, and alert a human when it trips. Test this deliberately by forcing errors in sandbox.
Comparing approaches to testing AI agents for ERP
No single testing method is enough. The table below compares the four main approaches and what each one misses.
| Approach | What it catches | What it misses | Cost and effort |
|---|---|---|---|
| Manual review | Context errors a domain expert spots instantly, such as wrong department or odd coding | Rare cases, regressions after prompt changes, anything outside the sample reviewed | Low setup, high ongoing time; does not scale |
| Automated evals | Regressions, tool selection errors, argument mistakes across many cases | Anything not in the golden dataset; stale or clean test data hides real-world failures | Moderate setup to build the dataset; cheap to rerun |
| Shadow mode | Real production inputs, current data, and gaps between sandbox and production | Side effects of actual writes, such as triggered workflows or scripts, because nothing is committed | Needs comparison tooling and a period of parallel running |
| Staged rollout | True production behavior, including downstream automation and volume effects | Nothing is hidden, but errors now reach real books; limits blast radius only | Low extra build; highest risk if the earlier stages were skipped |
The practical sequence is evals first, then shadow mode, then a staged rollout limited to one record type, one subsidiary or a small share of volume. Manual review runs alongside all three, especially early on.
How do OWASP and the NIST AI RMF fit in?
You don’t need a framework to test an agent well. But frameworks give you shared language with security teams and auditors, and they catch categories of risk you might skip.
The OWASP Top 10 for LLM Applications is a community list of the most critical security risks in applications built on language models. For ERP agents, Prompt Injection (LLM01) and Excessive Agency (LLM06) are the most relevant entries. Use them as a checklist when designing adversarial eval cases and tool permissions.
The NIST AI Risk Management Framework (AI RMF 1.0) is a voluntary framework from the US National Institute of Standards and Technology. It organizes AI risk work into four functions: Govern, Map, Measure and Manage. NIST’s Generative AI Profile (NIST AI 600-1), published in 2024, extends it to generative AI. The Measure function is where your evals and shadow-mode results belong; Manage covers approval gates and incident response.
If your team runs formal security testing, add agent-specific cases to that scope rather than running a separate process.
Pre-production checklist for testing AI agents for ERP
Use this checklist as a go-live gate. If any item is unchecked, the agent stays in dry-run.
- The agent runs under a dedicated integration role, not an admin or personal account.
- Write permissions cover only the record types the use case needs.
- Tools map to specific business actions, with no generic API passthrough tool.
- The agent’s role is mapped against your segregation-of-duties matrix and approved by finance.
- A golden dataset includes hard cases and adversarial documents, and the latest eval run passes your agreed threshold.
- Dry-run mode is enforced in the tool code, not in the prompt.
- Shadow-mode results have been compared against human decisions and reviewed by the process owner.
- Every write carries an idempotency key and a source reference, and duplicate retries are tested.
- Human approval is required above defined thresholds and for sensitive fields such as bank details.
- Every agent-created record carries a run ID, and reversal has been tested end to end.
- Audit logs capture input, tool choice, arguments, approval and ERP response.
- Retry caps, a circuit breaker and alerting are in place and have been triggered in sandbox.
When an agent should not get write access yet
Some processes aren’t ready for an agent, however good the testing. If your team can’t agree on the correct outcome for a transaction, the agent can’t learn it either. Fix the process first.
The same applies when source data is unreliable. An agent that creates records from messy CRM data will create messy ERP records faster. Clean CRM-to-ERP sync is often the real prerequisite; our CRM integration work usually starts there.
Finally, if a deterministic workflow can do the job, use it. A rules-based sync in n8n or an iPaaS is easier to test, audit and explain. Reserve agents for steps that need judgment, such as reading unstructured documents, and keep the actual write in deterministic code. Our walkthrough on building an AI agent in n8n that updates HubSpot shows that split in practice.
Getting to a go-live decision
Treat write access as something an agent earns in stages: read-only, dry-run, shadow mode, then narrow writes with approval. Each stage should produce evidence your finance and IT leads can review. If you want a second opinion on an agent before it touches your books, our AI agents and automation team can run a readiness review against the checklist above. Contact Integr8e to book one.
Useful answers
Frequently Asked Questions
Can I test an AI agent directly in my production ERP?
Only in dry-run or shadow mode, where the agent reads production data but your code blocks every write. Letting an untested agent commit records to production risks duplicates and misposted transactions that must be reversed manually. Use a sandbox for functional testing, then shadow mode against production inputs before granting any real write access.
How many test cases does a golden dataset need?
There is no fixed number. The dataset should cover every record type the agent writes, every entity or subsidiary it touches, and the known hard cases: multi-currency, partial quantities, near-duplicate vendors, and closed periods. Coverage of difficult scenarios matters more than raw volume. Add every production error the agent makes as a new test case.
What is the difference between dry-run mode and shadow mode?
Dry-run mode means the agent builds write requests that your code logs instead of sending. Shadow mode runs dry-run against live production inputs, in parallel with your human team, so you can compare the agent’s proposed writes with what people actually did. Dry-run checks mechanics; shadow mode checks real-world accuracy.
Does using MCP make an ERP agent safer?
Not by itself. The Model Context Protocol standardizes how tools are exposed to a model, but safety depends on which tools you expose and how narrowly they are scoped. An MCP server offering a generic API passthrough is as risky as direct API access. Narrow, action-specific tools with approval gates are what reduce risk.
Should an AI agent ever approve ERP transactions?
In most finance processes, no. Segregation of duties requires that the person or system creating a transaction differs from the one approving it. An agent can prepare drafts and flag exceptions, while a human with the right role approves. Changing this requires sign-off from finance leadership and, where relevant, your auditors.
How often should I rerun agent evals?
Rerun the full eval set whenever you change the model, the system prompt, a tool definition, or ERP configuration the agent depends on, such as new custom fields or approval rules. Also run it on a regular schedule, because upstream data and vendor behavior change over time even when your agent code does not.
Integr8e perspective
The best technology choice creates useful momentum without adding avoidable complexity.